Digital Transformation

Phillip Probert

Category: Perspectives

Was this really all my work?

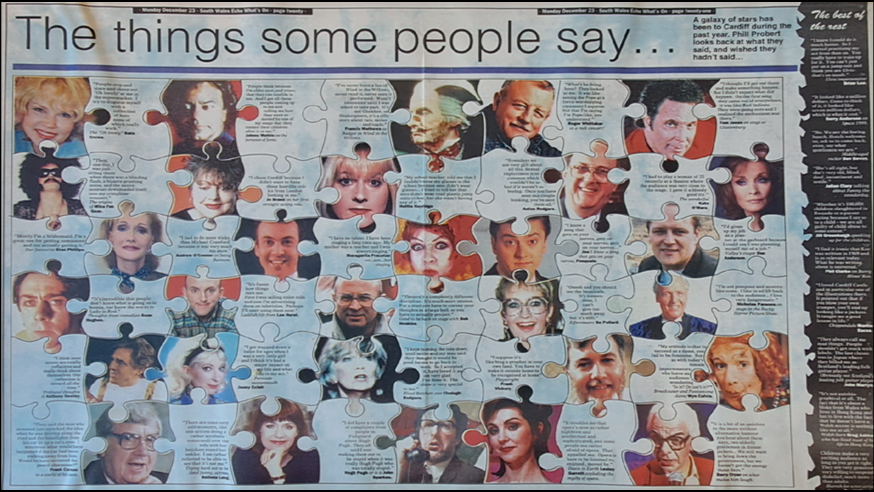
Centrespread from the South Wales Echo: What’s On – Christmas 1996

Headlines, AI Provenance, Design, and the 80/40 By-line

Before AI, and before the internet reshaped how we communicate, I worked as a graphic designer for a series of regional UK daily newspapers: the Newcastle Evening Chronicle, the South Wales Echo in Cardiff, and the Birmingham Evening Mail.

Producing a daily paper is an industrial production line. It usually starts out on the cold pavement with a reporter – full “Eddie Trenchcoat” style – chasing a lead. If the story warranted it, a photographer was sent along.

Their notes and photo rolls were fed back into the newsroom, where a small army of sub-editors chopped, checked, and polished the raw copy before passing it up to the chief sub and editor. They held the ultimate authority on where every piece lived: front page, page three, features, or sports and so on

Somewhere in the middle of that controlled chaos, the team needed the page designed.

That was my job. I had to merge raw stories, cropped photographs, and fixed ad blocks into a single coherent visual package. Multiply that by 36, 42, or however many pages were on the press schedule that afternoon, and send it down the line to be printed.

After eleven years, I moved on to other things (Another story for another day). Out of the thousands of pages I designed over a decade, I kept a thick portfolio of the ones I liked best.

And every so often, I look at them and ask the obvious question: Were they actually mine?

Well, technically, no. I didn’t write the headlines or the copy. I didn’t take the photos. I certainly didn’t run the printing press or drop the bundles on the corner newsagent’s curb. (Though I will still claim full bragging rights for an award-winning double-page spread in 1999.)

So why do I still think of them as mine?

Because they proved something specific: my ability to synthesise information and design at speed. I was good at it. The raw materials belonged to the newsroom, but the structure, balance, and visual hierarchy belonged to me. (And obviously as a part of a team of other designers)

When I transitioned into digital consultancy, that same underlying dynamic followed me. Working as a business analyst, project manager, and UX designer across digital transformation programs, you quickly learn that nothing meaningful is built in isolation.

When an online digital health dashboard goes live, or an agile delivery team hits its cadence, I know I didn’t build it alone. I didn’t write every line of code, configure every API, or map every database schema. My role has been to coordinate, design, facilitate, and keep the human intent clear amidst the technical noise.

To me – and likely to anyone who has spent decades working alongside production lines and software stacks – AI is simply another tool in the box.

It is a collaborator to be leveraged, pushed, and occasionally abused. In that sense, an LLM isn’t fundamentally different from a pocket calculator. You can use a calculator to solve complex structural engineering equations, or you can turn it upside down to spell out 8008135. The tool doesn’t care; the intent belongs entirely to the user.

Which brings us to where we stand today.

With Article 50 of the EU AI Act establishing a binding legal standard for machine-readable watermarking, synthetic text detection, and provenance disclosure, the debate over whether we should label AI content is effectively over.

The legal and technical machinery is already in motion. Compliance is no longer a philosophical option; it is a software spec.

So here is the final consultant’s summary – and the question we haven’t quite figured out how to answer:

If 80% of this essay originated in my own human memory, career history, and personal philosophy, but 20% was augmented, structured, or polished by a generative language model… does that disqualify me?

Does it invalidate all the observations made on the page?

If a watermark tags this text as “AI-Assisted,” does the reader discard the eleven years I spent in regional newsrooms?

Or do we accept that human authorship has always been a craft of orchestration, assembly, and final editorial responsibility?

I don’t have the answer. But the page is printed, and I’m putting my name on it.

First: LinkiedIn – August 15, 2026
Article 50 of the EU AI Act

Article 50 of the EU AI Act isn’t a suggestion, it is a binding, mechanical mandate. It tells everyone to “do as they are told.” But when you look at how it actually applies across media, the disconnect between bureaucratic theory and operational reality becomes glaring.

Article 50, The Poll, and The Watermark on the Slop Engine

There was a poll on LinkedIn. The question was simple enough:

“Claude is adding a watermark to AI text. Should AI-generated content be identifiable by default?”

  1. 👍 Yes. Better transparency
  2. 👎 No. Judge the content
  3. 🤔 Only with disclosure
  4. 🔐 Yes. Provenance matters

The funny thing about the poll is that as a binary choice, but the answer isn’t binary. As paradoxically, every single option can correct depending on where you stand.

Why?

  • Provenance matters when you are verifying deepfakes, legal filings, or state-sponsored disinformation.
  • Transparency matters when a digital transformation client needs to know if software documentation was hallucinatory or audited.
  • Disclosure matters in social discourse to separate honest co-creation from lazy deception.
  • Judge the content matters when a human writer uses a tool to polish syntax, fix typos, or bounce ideas off a wall.

While we debate the philosophy of polls, the law has already decided for us. Article 50 of the EU AI Act has arrived, and its message is blunt: Do as you are told.

But what does Article 50 Actually say?

Under Article 50, providers and deployers of AI systems face strict transparency obligations across all media formats:

  • Text: Synthetic text published to inform the public on matters of public interest must be disclosed as artificially generated or manipulated, unless it has undergone human editorial review and a natural person holds legal responsibility.
  • Images & Audio/Video (Deepfakes): Any artificial or manipulated content that significantly resembles real people, places, or events must be prominently labelled as artificially created or altered.
  • Machine-Readable Provenance: AI generators must mark their outputs in a technical, machine-readable format (such as C2PA metadata) so downstream platforms can detect them automatically.

On paper, this sounds like clean, sensible regulation. In practice, it creates a bizarre double standard across our media ecosystem and the desire for LinkedIn to reduce the amount of ‘AI slop’ that is presented through the platform

The Christmas 1996 Test

Back in Christmas 1996, I designed a double-page spread for a regional daily newspaper summarizing the “Quotes of the Year.”

I didn’t utter a single one of those quotes. A sub-editor gathered them from news wires, and I spent a few hours arranging the typography, balancing white space, and building a visual hierarchy.

The raw material belonged to the newsroom, but the structure, assembly, and presentation belonged to me. Nobody demanded a watermark saying “This page contains 0% original speech.” We understood that human craft lives in orchestration, curation, and final editorial judgment.

Fast forward to 2026. If a digital consultant uses an LLM to help structure a complex 2,000-word essay drawn from 30 years of career history, compliance hawks demand a watermark. Fair enough

Meanwhile…

What does the LinkedIn platform algorithm actually amplify?

Search LinkedIn today and you will find dozens of accounts posting the exact same graphic of a CV, complete with hallucinated LLM typos (“finescial,” “meusu”), claiming a “98% ATS score.”

It is literal machine slop, posted by humans acting like low-level spammers to sell fake resume rewrites to desperate job seekers. (And that’s just one of the many types of ‘slop’ that we all experience.)

So what we find is the following

  • Compliance Ideal = Demands watermarks on human-edited, highly polished prose.
  • Platform Reality = Pushes un-watermarked, copy-pasted, hallucinated scam templates.

Do as you are told

Article 50 will force platforms to tag synthetic media at the model layer. Machine-readable metadata will be baked into pixel buffers and text streams. And that is fine. Compliance is a spec. We will follow the rules.

But a technical watermark on an output file will never replace human editorial judgment. It won’t stop engagement farms from exploiting job seekers, and it won’t tell you whether an essay was born from genuine reflection – like sitting on a hot rail-replacement bus to Aberystwyth during a solar eclipse – or generated by a prompt-dump.

So, go ahead and mandate the tags. Label the files. Follow Article 50.

Because when the watermarks are applied to everything, readers will eventually have to do what they should have been doing all along: Stop auditing the ink, read the page, and judge the content.


This essay blends intentional human curation with AI‑assisted support; all synthetic content is intentionally disclosed.

First: LinkedIn August 17, 2026

Powered by WordPress & Theme by Anders Norén